 Athena Engine 1.0
Frontier-class models on a desktop computer
Athena Engine runs models that usually live in data centers on a single NVIDIA GB10: a DGX Spark or an ASUS Ascent GX10. Fast enough for real work: long documents, long conversations, agents.
Measured on a GB10
Models
Four models, one name
The API always serves the model as "Athena": configure your clients once, and they keep working when you switch from DeepSeek to Qwen.
The main model for long conversations and agents.
The same model, reading images too.
Reads images and documents (PDF, DOCX, Markdown, HTML) alongside the text.
340 GiB on a 128 GB machine: the engine keeps in memory what every token reads and fetches the rest from the SSD. 14.8 tokens per second.
New in 1.0
More than chat: a whole machine of services
It speaks and listens
OpenAI's audio routes with Qwen3-TTS and Qwen3-ASR: the first audio leaves in 0.06 s, and 12 seconds of speech are transcribed in 0.6 s.
Multimodal search
EmbeddingGemma 2 puts text, pictures, video and sound in one space: a search in words finds a photo, a clip or a recording. Rerank included.
Video with sound
Lightricks' LTX 2.5 makes clips with their sound from a description or a picture, up to Full HD. Four seconds in about 100 s, with the chat running.
The memory guardian
Voice, conversations, search and video ask one guardian for memory, by priority. A conversation that is working is never starved.
No conversation read twice
Context stays on disk and comes back in a moment, even after a restart. Agents resume from the prefix already read, turn after turn.
Compatible with what you use
OpenAI- and Anthropic-compatible endpoints with streaming and tool calls: the clients and agents you already use work unchanged.
Install
Ready in minutes
With Docker, from the public image, or with the install script. Full instructions, the models and the APIs are in the README.
The API key is optional, and there is a guide to put HTTPS in front of the engine. Free for personal use, research, education, and for developers and small companies at work.
Athena Engine on GitHub →docker pull ghcr.io/xangel82/athena-engine:1.0.0
With Athena Logos
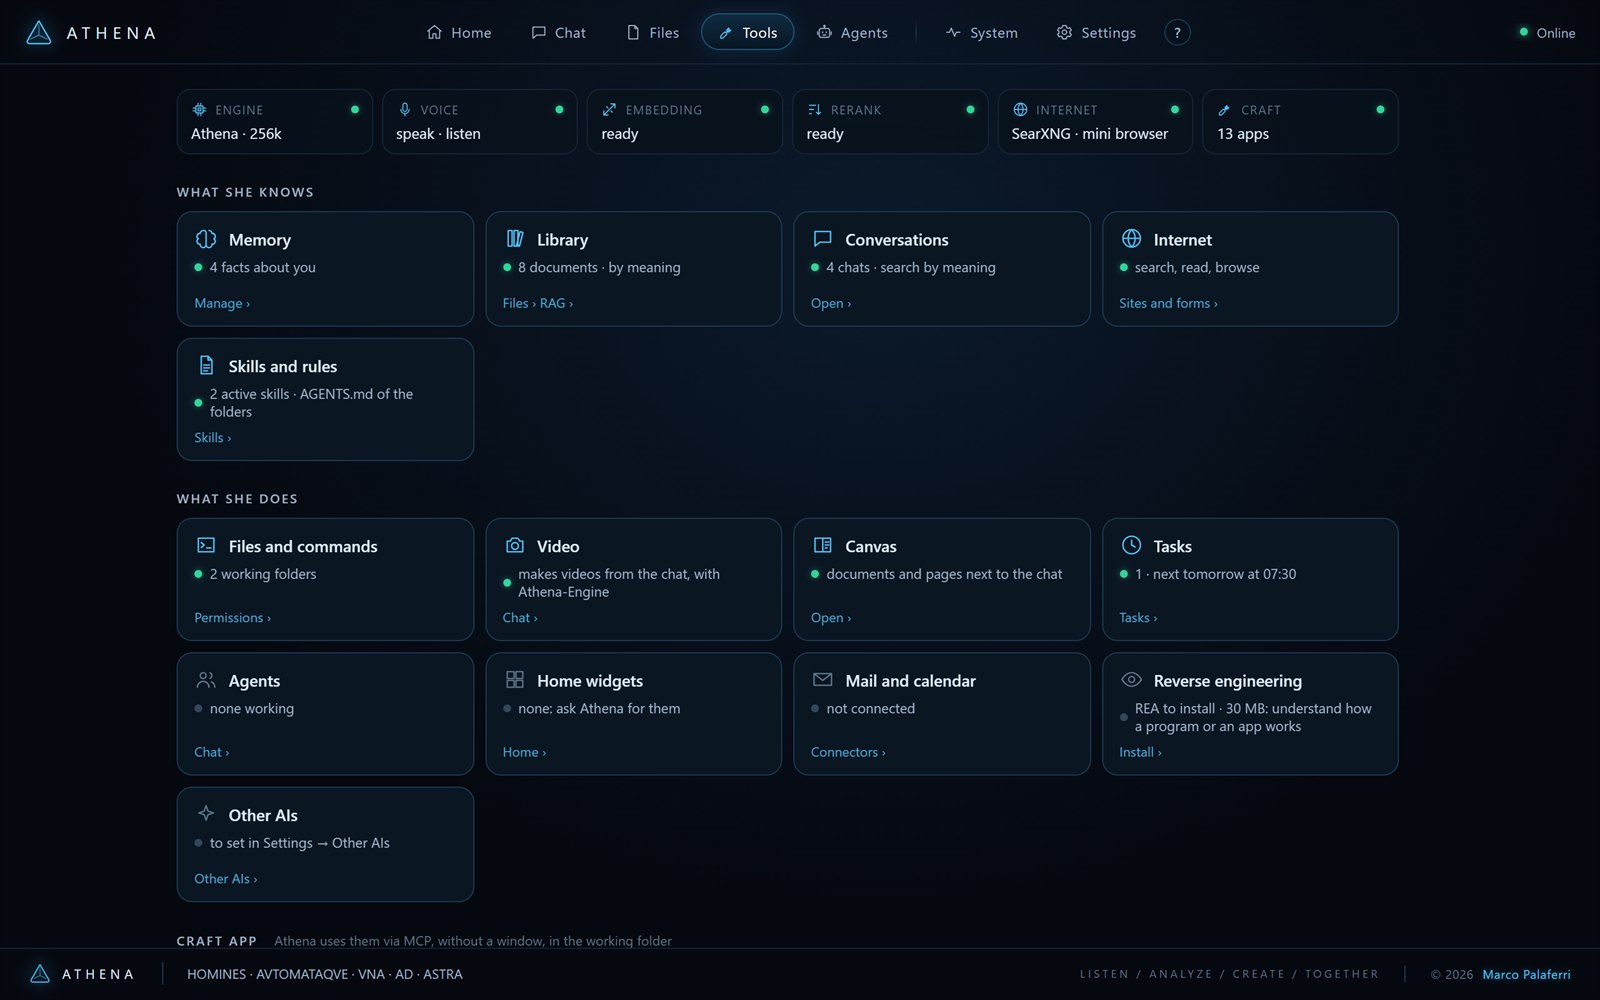
The engine runs the models; Athena Logos is the assistant built on top. It uses the chat, the voice, search, video and the system companion's model switch.